
AI cloud and GPU providers
The computing will come from AI cloud operators, hyperscalers, sovereign AI programmes and enterprises.
What the project needs
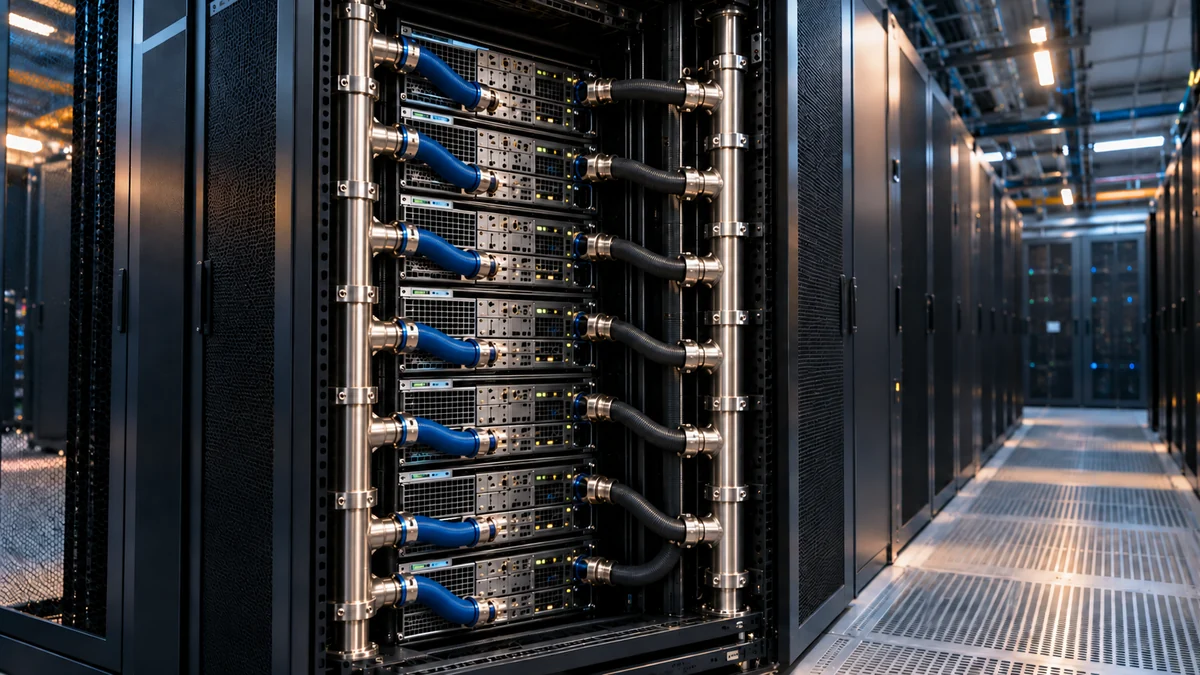
GPU cloud operators running training and batch inference are natural tenants for an AI campus of this kind: racks of 120 to 140 kW, liquid cooled, on a campus designed for AI from the first drawing.
Phase 1 is 100 MW, on a site with land to expand in later phases.
Who it suits
Organisations such as:
- GPU cloud and GPU-as-a-service providers
- AI compute providers and neoclouds
- Model training and inference platforms
- AI companies with their own compute needs
How it connects to the campus
What to show
At registration, tell us about up to three comparable assignments, completed or in operation, with the year, location, your role, the scale in the measure that fits your discipline, the status and a way to verify it. Newer specialist firms are welcome to present documented pilots and the founding team's record, clearly labelled.
Clusters you have deployed, number and generation of accelerators, rack density and cooling architecture, training versus inference mix, and any sovereign or public compute credentials.
How to take part
-
Register your interest
Tell us about your organisation and your area of interest.
-
A conversation
We will arrange a confidential discussion to explore fit and opportunities.
-
The data room
Selected organisations will be invited to a data room with further information.
Selected organisations receive, through the data room, the engineering envelope and the reference-design interfaces for their role.
Also in Compute and cloud